01Machine learning · Research & engineering

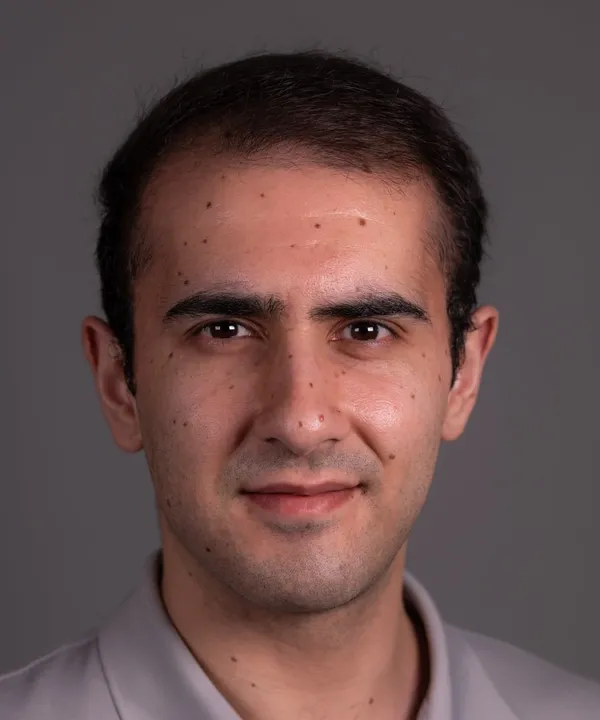
Nick Kashani Motlagh. I build LLM and retrieval systems that know when not to answer.

PhD, Ohio State (2026). I built LoRA-trained policies that decide when a RAG system should revise its answer, evaluated on 25,870 questions, and a reject-option method that won a Springer Best Paper Award.

FIG.0 1,000 CIFAR-100 test predictions, grown to their confidence. Below the line, the model says “I don’t know.” Try the threshold

Available nowfor Research Scientist,Research Engineer,ML Engineer,Applied Scientist,SWE (AI)

SF Bay Area / NYC.U.S. citizen

1.1 The short version

Status
Available now
Roles
Research Scientist Research Engineer Machine Learning Engineer Applied Scientist Software Engineer (AI)
Where
San Francisco Bay Area or New York City. Based in Columbus, Ohio; open to relocating.
Work auth
U.S. citizen. No sponsorship needed.
Education
PhD, Computer Science and Engineering, Ohio State, Aug 2026. Advisor Prof. Jim Davis; minors in Mathematics and HPC.
Now
Computer Engineer II, DCS Corp. AFRL-sponsored, since May 2025.
Papers
4 first-author, peer-reviewed. Springer Best Paper Award, ISVC 2022.

1.2 Skills, and where I used them

LLMs & post-training

LoRA / PEFT Teacher-model synthetic data vLLM HF Transformers

LoRA-trained scorers that choose answer, revise, or abstain; evidence-grounded QA models trained on teacher-generated data at DCS. Evidence: RAG revision DCS role

Retrieval

DPR dense retrieval BM25 MonoT5 reranking FAISS

Three Wikipedia retrieval setups behind a 25,870-question evaluation. Evidence: RAG revision

Evaluation

Paired outcomes Seeds + paired t-tests Bootstrap intervals LLM-as-judge Selective prediction Calibration (ECE, Brier)

3 seeds with paired t-tests and 10,000-replicate bootstraps; a reimplementation checked against its reference by 37 parity tests. Evidence: RAG revision Reject option

Vision

ViTs Linear probes on DINOv2, DINOv3, SigLIP 2 Self-supervised pretraining

Probes on four frozen ViT backbones; self-supervised vision models at AFRL in 2024. Evidence: Backbone re-run AFRL 2024

Engineering

Python PyTorch NumPy Slurm Singularity uv Git Linux HPC TypeScript

Ported the B-CDF rule from Python to TypeScript for the live demo; Slurm GPU jobs for the RAG study. Evidence: Live demo RAG revision

2.1 Selected work

What I’ve built. Scale, stack, and status for each.

  1. Dissertation capstone

    A two-by-two grid of paired outcomes. A right draft that stays right is preserved; a right draft that revision makes wrong is harmed; a wrong draft that revision fixes is repaired; a wrong draft that stays wrong is unrecovered. AFTER REVISION → RIGHT WRONG DRAFT ↓ RIGHT WRONG PRESERVED HARMED REPAIRED UNRECOVERED +1 −1 BOTH BRANCHES, SAME QUESTION
    Net accuracy change = repaired − harmed

    Should a RAG system keep its draft or revise it?

    Revision can repair a wrong answer or harm a right one. The system has to choose before paying for the full revision.

    What I built

    • A paired-outcome evaluation on 25,870 held-out questions from NQ-Open, TriviaQA, and PopQA. Each answer is scored as preserved, repaired, harmed, or unrecovered.
    • Three retrieval setups over Wikipedia: DPR dense retrieval, BM25, and BM25→MonoT5 reranking. Llama 3.1 8B Instruct drafts and revises, Llama 3.3 70B Instruct judges, and gpt-oss-20b and OLMo 3 7B are secondary generators.
    • LoRA-trained scorers that choose answer or revise, plus abstain in a three-action menu.
    • 3 training seeds with paired run-level t-tests, and 10,000-replicate bootstrap intervals for baselines. Thresholds are picked on dev and frozen before test.
    • PyTorch
    • HF Transformers
    • LoRA
    • vLLM
    • FAISS
    • Slurm

    Unpublished Unpublished. Revised after ACL Rolling Review; arXiv version in preparation. Code and artifacts will not be released.

  2. ISVC 2022 · MVA 2025 · 2026

    Dot columns of predictions by confidence, cut by a vertical threshold: hollow dots on the left are declined, filled dots on the right are answered. τ 0 1 DECLINE ANSWER CONFIDENCE
    Declined guesses are no better than a coin flip

    Reject-option classification, from Best Paper to live demo

    A classifier should decline its least reliable predictions without a hand-set rejection cost or coverage target.

    The method · 2022

    • Per-class softmax thresholds learned from validation data with a binomial-CDF test: keep declining only while the declined predictions are no better than a coin flip.
    • On CIFAR-100, selective accuracy rises from 88.3% to 97.8% at 77.3% coverage. The journal extension covers 4 vision, 3 text, and 8 synthetic datasets.

    The 2026 re-run

    • Linear probes on 4 frozen backbones (DINOv2 ViT-S/14 and ViT-B/14, DINOv3 ViT-S/16, SigLIP 2 ViT-B/16), logits from a local RTX 4090, and a fast NumPy B-CDF matched to the reference by 37 parity tests.

    The demo

    • Ported the rule to TypeScript and checked it against the Python reference. It runs this site’s live demo: 1,000 test images, a draggable threshold, and δ controls.
    • Python
    • PyTorch
    • timm
    • NumPy
    • uv
    • TypeScript

    Best Paper · Code public Method peer-reviewed: Springer Best Paper Award at ISVC 2022, journal extension in Machine Vision and Applications (2025). The 2026 re-run is public code, not peer-reviewed.

  3. WMT 2024

    An image and a swapped counterpart feed the same model; the figure asks how much the output changes. MODEL Δ IMAGE SWAPPED ⇄
    Swap the image, measure the change

    Does a multimodal translation model use the image?

    Translation scores alone can’t show whether a model reads the image or ignores it.

    What I built

    • ImageCoMMuTE: contrastive metrics that hold a candidate translation fixed and swap in matched or mismatched images, separating visual understanding from the final translation decision.
    • Evaluated three English-to-French multimodal model families, plus gated variants.
    • The best system (VGAMT) reads the image correctly 81% of the time, but that changes its translation preference only 63% of the time.

    Peer-reviewed Peer-reviewed, WMT 2024.

Also public

2.2Live demo · ISVC 2022 Best Paper

Stop answering where the answers become coin flips.

Sort a classifier’s guesses by confidence and decline the least sure ones. The rule from Learning When to Say “I Don’t Know” keeps declining only while the declined guesses are no better than a coin flip. The paper fits a line per class; this demo uses one line for all 100 classes. Drag it.

1,000 of the 10,000 test images, one dot each, placed by the model’s confidence. Mistakes stack at the bottom of each column; hollow dots are declined. The dashed line is where the rule put the threshold. Hover or press the arrow keys to inspect an image.

Answers
78.7%
7,868 of 10,000 test images
Right when it answers
95.7%
vs 86.1% answering everything
Right when it declines
50.6%
no better than a coin flip
Coin-flip test · δ

δ is the test’s significance level. Low: decline anything not clearly better than a coin flip. High: decline only what is clearly worse than one.

No better than a coin flip: the declined guesses were right 50.6% of the time, so declining them gives up almost nothing.

Model: DINOv2 ViT-S/14 (frozen) + linear probe, temperature-scaled. Data: CIFAR-100. The line is learned on 10,000 held-out training images; every number here is measured on the 10,000 test images, of which the plot shows 1,000.

03 Research

Peer-reviewed publications. 4 first-author papers, 2021–2025.

  1. 2025 Machine Vision and Applications

    Naturally Constrained Reject Option Classification

    N. Kashani Motlagh, J. Davis, T. Anderson, J. Gwinnup

  2. 2024 WMT 2024

    Assessing the Role of Imagery in Multimodal Machine Translation

    N. Kashani Motlagh, J. Davis, J. Gwinnup, G. Erdmann, T. Anderson

  3. 2021 ICCV 2021 Workshop on LUAI

    A Framework for Semi-automatic Collection of Temporal Satellite Imagery for Analysis of Dynamic Regions

    N. Kashani Motlagh, A. Radhakrishnan, J. Davis, R. Ilin

04 Experience

AFRL-sponsored ML research every year since 2020. DCS Corp since May 2025; Ohio State’s Computer Vision Lab, 2021–2026.

Computer Engineer II — DCS Corp

AFRL-sponsored · Dayton, OH / May 2025 — Present

  1. Build evidence-grounded QA systems: small open models answer from retrieved documents, cite the passage they used, and abstain when the evidence doesn’t support an answer. Uses synthetic training data from a teacher model, LoRA fine-tuning, and paired base-versus-adapted evaluation on held-out questions.
  2. Build paired-outcome evaluation pipelines for retrieval-augmented QA that measure, on 25,870 held-out questions, when revision repairs a wrong answer and when it harms a right one.
  3. Train and evaluate LoRA fine-tuned models for answer, refine, and abstain decisions with PyTorch, Hugging Face, and Slurm, comparing policy variants on coverage, utility, and out-of-distribution behavior.

Graduate Research Associate — Computer Vision Lab

Ohio State University · Columbus, OH / Aug 2021 — Aug 2026

  1. Built selective-prediction systems and reproducible experiments for vision, multimodal, and language tasks, advised by Prof. Jim Davis.
  2. Developed per-class reject-option classification and released public research code. Springer Best Paper Award at ISVC 2022; extended in Machine Vision and Applications, 2025.
  3. Designed ImageCoMMuTE evaluation metrics to separate visual evidence use from final translation decisions (WMT 2024).
  4. Published first-author papers on selective prediction, multimodal evaluation, and satellite imagery collection.
Nick Kashani Motlagh
Nick Kashani Motlagh · Columbus, Ohio

05 Get in touch

Available now.

Research Scientist, Research Engineer, ML Engineer, Applied Scientist, and SWE (AI) roles in the San Francisco Bay Area or New York City.

Based in
Columbus, Ohio open to relocating
Work auth
U.S. citizen no sponsorship needed